Profile
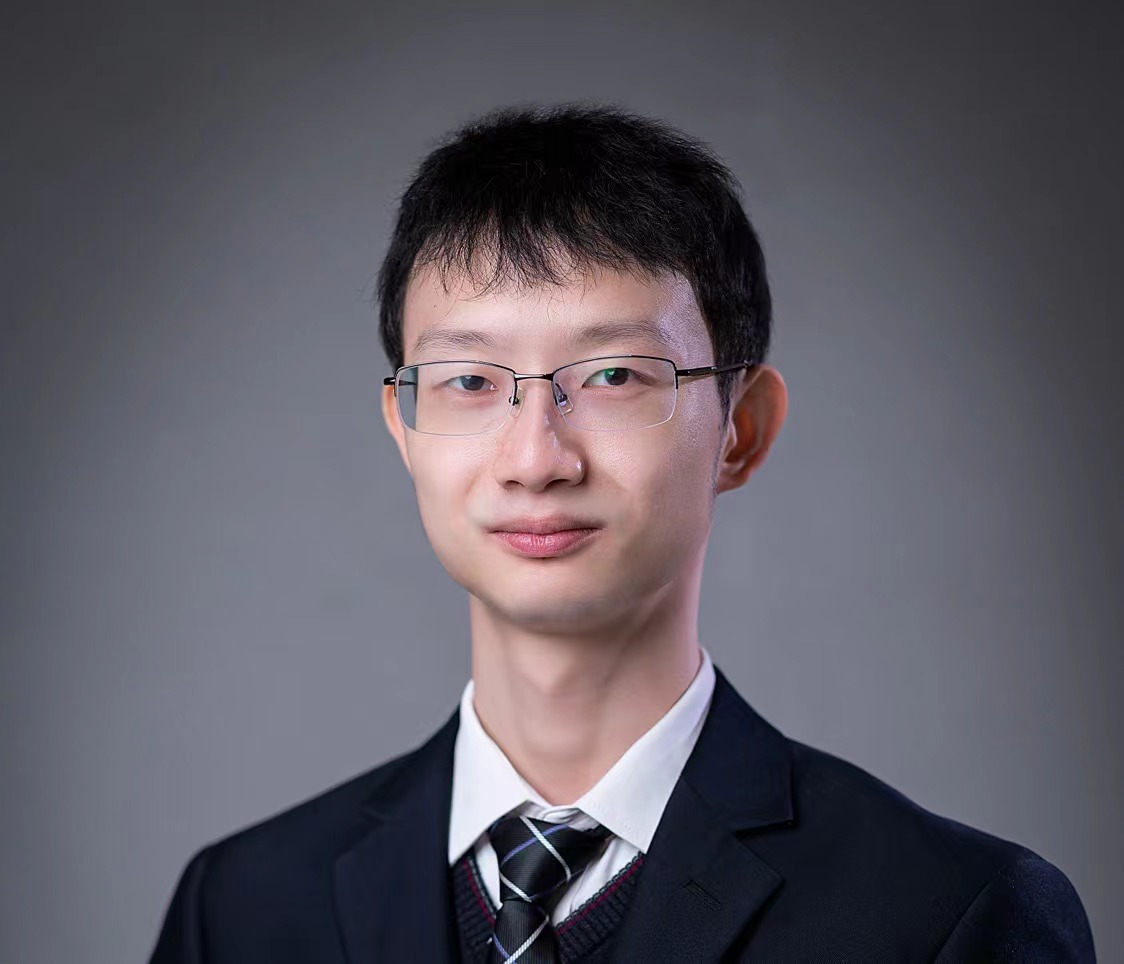
I am a tenure-track assistant professor at Shanghai Jiao Tong University. I am a member of Institute of Artificial Intelligence and Cognitive Security, where I work closely with Prof. Gongshen Liu. I received my Ph.D. (2023) and M.S. (2020) degrees from Shanghai Jiao Tong University, advised by Prof. Hai Zhao. I enjoyed research internships at Amazon Web Services (with Aston Zhang), Microsoft Research Redmond (with Chenguang Zhu), Langboat Tech (with Ming Zhou), and NICT (with Masao Utiyama). I have served as an action editor for ACL Rolling Review (ARR), Transactions on Machine Learning Research (TMLR). I regularly served as (Senior) Area Chair or Senior Program Committee of top-tier conferences such as ACL, NeurIPS, and EMNLP.
My research interests include natural language processing, LLM reasoning, LLM agents, and LLM safety. I have published over 100 papers in top-tier conferences and journals, including Nature Communications, TPAMI, ICML, ICLR, ACL, AAAI, EMNLP, TNNLS, TASLP, and COLING. I have won 1st place in various language understanding and reasoning leaderboards, such as SQuAD2.0, MuTual, RACE, ShARC, and CMRC. I was awarded as an Academic Star at Shanghai Jiao Tong University and was selected as one of the Global Top 100 Chinese Rising Stars in Artificial Intelligence. I won the Excellent Doctoral Thesis of Chinese Information Processing Society (CIPS), WAIC 2024 Youth Outstanding Paper Award, WAIC 2024 YunFan Award: Bright Star, and Baidu Scholarship.
Recent Projects
- Recursive Self Improvement (RSI): Environment Scaling, Continual Learning, Generalization
- Agent Interaction: GUI Agents, Human-Agent Collaboration, Multi-Agent Interaction, Generative UI
- Agent OS: Parallel Scheduling for Massive Agents, Context Management
- Agent Safety & Robustness: Environmental Injection, Over-Competition, Recursive Alignment
Teaching
Courses:- NIS3353: Artificial Intelligence Security
Undergraduate, Shanghai Jiao Tong University, 2024- - NIS8021: Frontier Technology in Natural Language Processing
Graduate, Shanghai Jiao Tong University, 2024-
- For Beginners: Dive into LLMs《动手学大模型》系列编程实践教程 New Updates! (May 2025)
- CVPR 2024: From Multimodal LLM to Human-level AI: Modality, Instruction, Reasoning and Beyond
Hao Fei, Yuan Yao, Ao Zhang, Haotian Liu, Fuxiao Liu, Zhuosheng Zhang, Shuicheng Yan.
Seattle WA, USA
[Website] - LREC-COLING 2024: From Multimodal LLM to Human-level AI: Modality, Instruction, Reasoning, Efficiency and Beyond
Hao Fei, Yuan Yao, Zhuosheng Zhang, Fuxiao Liu, Ao Zhang, Tat-Seng Chua.
Torino, Italia
[Website] - IJCNLP-AACL 2023: Learning WHO Saying WHAT to WHOM in Multi-Party Conversations
Jia-Chen Gu, Zhuosheng Zhang, and Zhen-Hua Ling.
Bali, Indonesia.
[Website] - IJCAI 2021: Machine Reading Comprehension: The Role of Contextualized Language Models and Beyond
Zhuosheng Zhang and Hai Zhao.
Montreal, Canada (Virtual)
[Website]
Selected Publications
Discover |
 |
 .
* Corresponding author; # Equal contribution.
-
Automatic Chain of Thought Prompting in Large Language Models
Zhuosheng Zhang*, Aston Zhang*, Mu Li, Alex Smola.
ICLR, 2023
"Let's think not just step by step, but also one by one."
[Paper] [arXiv] [Slides] [Post] [Video] []Paper Digest: Most Influential ICLR 2023 Papers (2023-09)·Featured in Dive into Deep Learning
Large language models (LLMs) can perform complex reasoning by generating intermediate reasoning steps. Providing these steps for prompting demonstrations is called chain-of-thought (CoT) prompting. CoT prompting has two major paradigms. One leverages a simple prompt like "Let's think step by step" to facilitate step-by-step thinking before answering a question. The other uses a few manual demonstrations one by one, each composed of a question and a reasoning chain that leads to an answer. The superior performance of the second paradigm hinges on the hand-crafting of task-specific demonstrations one by one. We show that such manual efforts may be eliminated by leveraging LLMs with the "Let's think step by step" prompt to generate reasoning chains for demonstrations one by one, i.e., let's think not just step by step, but also one by one. However, these generated chains often come with mistakes. To mitigate the effect of such mistakes, we find that diversity matters for automatically constructing demonstrations. We propose an automatic CoT prompting method: Auto-CoT. It samples questions with diversity and generates reasoning chains to construct demonstrations. On ten public benchmark reasoning tasks with GPT-3, Auto-CoT consistently matches or exceeds the performance of the CoT paradigm that requires manual designs of demonstrations. Code is available at https://github.com/amazon-science/auto-cot
-
Multimodal Chain-of-Thought Reasoning in Language Models
Zhuosheng Zhang*, Aston Zhang*, Mu Li, Hai Zhao, George Karypis, Alex Smola.
TMLR, 2024
"Imagine learning a textbook with no figures: Multimodal-CoT surpasses humans on ScienceQA."
[Paper] [arXiv] [Post] [Trending Research] [Idea Inspiration] []Required reading in CMU 11-877 (Spring 2023)·Featured in Dive into Deep Learning
Large language models (LLMs) have shown impressive performance on complex reasoning by leveraging chain-of-thought (CoT) prompting to generate intermediate reasoning chains as the rationale to infer the answer. However, existing CoT studies are mostly isolated in the language modality with LLMs, where LLMs are hard to deploy. To elicit CoT reasoning in multimodality, a possible solution is to fine-tune small language models by fusing the vision and language features to perform CoT reasoning. The key challenge is that those language models tend to generate hallucinated reasoning chains that mislead the answer inference. To mitigate the effect of such mistakes, we propose Multimodal-CoT that incorporates vision features in a decoupled training framework. The framework separates the rationale generation and answer inference into two stages. By incorporating the vision features in both stages, the model is able to generate effective rationales that contribute to answer inference. With Multimodal-CoT, our model under 1 billion parameters outperforms the previous state-of-the-art LLM (GPT-3.5) by 16% (75.17%->91.68%) on the ScienceQA benchmark and even surpasses human performance. Code is publicly available at https://github.com/amazon-science/mm-cot.
-
Mengzi: Towards Lightweight yet Ingenious Pre-trained Models for Chinese
Zhuosheng Zhang, Hanqing Zhang, Keming Chen, Yuhang Guo, Jingyun Hua, Yulong Wang, Ming Zhou.
Technical Report, 2021
[Paper] []Mengzi544Models2.6mtotal
Langboat/mengzi-bert-L6-H7685,601Langboat/mengzi-bert-base-fin145,652Langboat/mengzi-bert-base2,067,412Langboat/mengzi-oscar-base-caption1,338Langboat/mengzi-oscar-base-retrieval1,027Langboat/mengzi-oscar-base1,472Langboat/mengzi-t5-base-mt123,230Langboat/mengzi-t5-base219,357Cumulative downloads across 8 model repositories. Each repository is counted once; downloads are not unique users.
Although pre-trained models (PLMs) have achieved remarkable improvements in a wide range of NLP tasks, they are expensive in terms of time and resources. This calls for the study of training more efficient models with less computation but still ensures impressive performance. Instead of pursuing a larger scale, we are committed to developing lightweight yet more powerful models trained with equal or less computation and friendly to rapid deployment. This technical report releases our pre-trained model called Mengzi, which stands for a family of discriminative, generative, domain-specific, and multimodal pre-trained model variants, capable of a wide range of language and vision tasks. Compared with public Chinese PLMs, Mengzi is simple but more powerful. Our lightweight model has achieved new state-of-the-art results on the widely-used CLUE benchmark with our optimized pre-training and fine-tuning techniques. Without modifying the model architecture, our model can be easily employed as an alternative to existing PLMs. Our sources are available at https://github.com/Langboat/Mengzi.
-
R-Judge: Benchmarking Safety Risk Awareness for LLM Agents
Tongxin Yuan#, Zhiwei He#, Lingzhong Dong, Yiming Wang, Ruijie Zhao, Tian Xia, Lizhen Xu, Binglin Zhou, Fangqi Li, Zhuosheng Zhang*, Rui Wang, Gongshen Liu.
EMNLP, 2024
[Paper] [arXiv] [PDF] []Evaluation benchmark for Shanghai AI Lab’s AgentDoG
Large language models (LLMs) have exhibited great potential in autonomously completing tasks across real-world applications. Despite this, these LLM agents introduce unexpected safety risks when operating in interactive environments. Instead of centering on the harmlessness of LLM-generated content in most prior studies, this work addresses the imperative need for benchmarking the behavioral safety of LLM agents within diverse environments. We introduce R-Judge, a benchmark crafted to evaluate the proficiency of LLMs in judging and identifying safety risks given agent interaction records. R-Judge comprises 569 records of multi-turn agent interaction, encompassing 27 key risk scenarios among 5 application categories and 10 risk types. It is of high-quality curation with annotated safety labels and risk descriptions. Evaluation of 11 LLMs on R-Judge shows considerable room for enhancing the risk awareness of LLMs: The best-performing model, GPT-4o, achieves 74.42% while no other models significantly exceed the random. Moreover, we reveal that risk awareness in open agent scenarios is a multi-dimensional capability involving knowledge and reasoning, thus challenging for LLMs. With further experiments, we find that fine-tuning on safety judgment significantly improve model performance while straightforward prompting mechanisms fail. R-Judge is publicly available at Annoymous.
-
Risks of AI Scientists: Prioritizing Safeguarding Over Autonomy
Xiangru Tang, Qiao Jin, Kunlun Zhu, Tongxin Yuan, Yichi Zhang, Wangchunshu Zhou, Meng Qu, Yilun Zhao, Jian Tang, Zhuosheng Zhang, Arman Cohan, Dov Greenbaum, Zhiyong Lu, Mark Gerstein*.
Nature Communications, 2025
[Paper] [arXiv] []Intelligent agents powered by large language models (LLMs) have demonstrated substantial promise in autonomously conducting experiments and facilitating scientific discoveries across various disciplines. While their capabilities are promising, they also introduce novel vulnerabilities that demand careful consideration for safety. However, there exists a notable gap in the literature, as there has been no comprehensive exploration of these vulnerabilities. This position paper fills this gap by conducting a thorough examination of vulnerabilities in LLM-based agents within scientific domains, shedding light on potential risks associated with their misuse and emphasizing the need for safety measures. We begin by providing a comprehensive overview of the potential risks inherent to scientific LLM agents, taking into account user intent, the specific scientific domain, and their potential impact on the external environment. Then, we delve into the origins of these vulnerabilities and provide a scoping review of the limited existing works. Based on our analysis, we propose a triadic framework involving human regulation, agent alignment, and an understanding of environmental feedback (agent regulation) to mitigate these identified risks. Furthermore, we highlight the limitations and challenges associated with safeguarding scientific agents and advocate for the development of improved models, robust benchmarks, and comprehensive regulations to address these issues effectively.
-
Semantics-Aware BERT for Language Understanding
Zhuosheng Zhang#, Yuwei Wu#, Hai Zhao*, Zuchao Li, Shuailiang Zhang, Xi Zhou, Xiang Zhou.
AAAI, 2020
[Paper] [arXiv] []Paper Digest: Most Influential AAAI 2020 Papers (2022-02)
The latest work on language representations carefully integrates contextualized features into language model training, which enables a series of success especially in various machine reading comprehension and natural language inference tasks. However, the existing language representation models including ELMo, GPT and BERT only exploit plain context-sensitive features such as character or word embeddings. They rarely consider incorporating structured semantic information which can provide rich semantics for language representation. To promote natural language understanding, we propose to incorporate explicit contextual semantics from pre-trained semantic role labeling, and introduce an improved language representation model, Semantics-aware BERT (SemBERT), which is capable of explicitly absorbing contextual semantics over a BERT backbone. SemBERT keeps the convenient usability of its BERT precursor in a light fine-tuning way without substantial task-specific modifications. Compared with BERT, semantics-aware BERT is as simple in concept but more powerful. It obtains new state-of-the-art or substantially improves results on ten reading comprehension and language inference tasks.
-
Retrospective Reader for Machine Reading Comprehension
Zhuosheng Zhang, Junjie Yang, Hai Zhao*.
AAAI, 2021
[Paper] [arXiv] [PDF] []Paper Digest: Most Influential AAAI 2021 Papers (2022-02)
Machine reading comprehension (MRC) is an AI challenge that requires machine to determine the correct answers to questions based on a given passage. MRC systems must not only answer question when necessary but also distinguish when no answer is available according to the given passage and then tactfully abstain from answering. When unanswerable questions are involved in the MRC task, an essential verification module called verifier is especially required in addition to the encoder, though the latest practice on MRC modeling still most benefits from adopting well pre-trained language models as the encoder block by only focusing on the "reading". This paper devotes itself to exploring better verifier design for the MRC task with unanswerable questions. Inspired by how humans solve reading comprehension questions, we proposed a retrospective reader (Retro-Reader) that integrates two stages of reading and verification strategies: 1) sketchy reading that briefly investigates the overall interactions of passage and question, and yield an initial judgment; 2) intensive reading that verifies the answer and gives the final prediction. The proposed reader is evaluated on two benchmark MRC challenge datasets SQuAD2.0 and NewsQA, achieving new state-of-the-art results. Significance tests show that our model is significantly better than the strong ELECTRA and ALBERT baselines. A series of analysis is also conducted to interpret the effectiveness of the proposed reader.
-
Is ChatGPT a General-Purpose Natural Language Processing Task Solver?
Chengwei Qin*, Aston Zhang*, Zhuosheng Zhang, Jiaao Chen, Michihiro Yasunaga, Diyi Yang.
EMNLP, 2023
[Paper] [arXiv] [PDF] []Paper Digest: 100 Must-Read NLP Papers (2016–2025)·Paper Digest: Most Influential EMNLP 2023 Papers (2026-03)
Spurred by advancements in scale, large language models (LLMs) have demonstrated the ability to perform a variety of natural language processing (NLP) tasks zero-shot—i.e., without adaptation on downstream data. Recently, the debut of ChatGPT has drawn a great deal of attention from the natural language processing (NLP) community due to the fact that it can generate high-quality responses to human input and self-correct previous mistakes based on subsequent conversations. However, it is not yet known whether ChatGPT can serve as a generalist model that can perform many NLP tasks zero-shot. In this work, we empirically analyze the zero-shot learning ability of ChatGPT by evaluating it on 20 popular NLP datasets covering 7 representative task categories. With extensive empirical studies, we demonstrate both the effectiveness and limitations of the current version of ChatGPT. We find that ChatGPT performs well on many tasks favoring reasoning capabilities (e.g., arithmetic reasoning) while it still faces challenges when solving specific tasks such as sequence tagging. We additionally provide in-depth analysis through qualitative case studies.
-
Thoughts Are All Over the Place: On the Underthinking of Long Reasoning Models
Yue Wang#, Qiuzhi Liu#, Jiahao Xu#, Tian Liang#, Xingyu Chen#, Zhiwei He#, Linfeng Song, Dian Yu, Juntao Li, Zhuosheng Zhang, Rui Wang, Zhaopeng Tu*, Haitao Mi, Dong Yu.
NeurIPS, 2025
[Paper] [arXiv] [PDF] []Paper Digest: Most Influential arXiv NLP Papers (2025-09)
Large language models (LLMs) such as OpenAI's o1 have demonstrated remarkable abilities in complex reasoning tasks by scaling test-time compute and exhibiting human-like deep thinking. However, we identify a phenomenon we term underthinking, where o1-like LLMs frequently switch between different reasoning thoughts without sufficiently exploring promising paths to reach a correct solution. This behavior leads to inadequate depth of reasoning and decreased performance, particularly on challenging mathematical problems. To systematically analyze this issue, we conduct experiments on three challenging test sets and two representative open-source o1-like models, revealing that frequent thought switching correlates with incorrect responses. We introduce a novel metric to quantify underthinking by measuring token efficiency in incorrect answers. To address underthinking, we propose a decoding strategy with thought switching penalty TIP that discourages premature transitions between thoughts, encouraging deeper exploration of each reasoning path. Experimental results demonstrate that our approach improves accuracy across challenging datasets without requiring model fine-tuning. Our findings contribute to understanding reasoning inefficiencies in o1-like LLMs and offer a practical solution to enhance their problem-solving capabilities.
-
DeepMath-103K: A Large-Scale, Challenging, Decontaminated, and Verifiable Mathematical Dataset for Advancing Reasoning
Zhiwei He#, Tian Liang#, Jiahao Xu#, Qiuzhi Liu, Xingyu Chen, Yue Wang, Linfeng Song, Dian Yu, Zhenwen Liang, Wenxuan Wang, Zhuosheng Zhang, Rui Wang*, Zhaopeng Tu*, Haitao Mi, Dong Yu.
ICLR, 2026
[Paper] [arXiv] []DeepMath301Models19.5ktotal
zwhe99/DeepMath-1.5B10,043zwhe99/DeepMath-Omn-1.5B562zwhe99/DeepMath-Zero-7B8,292zwhe99/DeepMath-Zero-Math-7B650Cumulative downloads across 4 model repositories. Each repository is counted once; downloads are not unique users.
Data171.5ktotal
zwhe99/DeepMath-103K171,508Cumulative downloads across 1 dataset repositories. Each repository is counted once; downloads are not unique users.
Positively featured by Jack Clark (Anthropic Co-founder)·Used in Thinking Machines Lab’s LoRA training study·CCL 2025 Hot Papers session
Reinforcement learning (RL) with large language models shows promise in complex reasoning. However, its progress is hindered by the lack of large-scale training data that is sufficiently challenging, contamination-free and verifiable. To this end, we introduce DeepMath-103K, a large-scale mathematical dataset designed with high difficulty (primarily levels 5-9), rigorous decontamination against numerous benchmarks, and verifiable answers for rule-based RL reward. It further includes three distinct R1 solutions adaptable for diverse training paradigms such as supervised fine-tuning (SFT). Spanning a wide range of mathematical topics, DeepMath-103K fosters the development of generalizable and advancing reasoning. Notably, models trained on DeepMath-103K achieve leading results on challenging mathematical benchmarks and demonstrate generalization beyond math such as biology, physics and chemistry, underscoring its broad efficacy.

-
On the Overscaling Curse of Parallel Thinking: System Efficacy Contradicts Sample Efficiency
Yiming Wang, Zhuosheng Zhang, Rui Wang.
NeurIPS, 2026
[Paper] [arXiv] []Parallel thinking improves LLM reasoning through multi-path sampling and aggregation. In standard evaluations, due to a lack of sample-specific priors, all samples share a global budget chosen to maximize dataset accuracy. However, many samples reach their best accuracy with much smaller budgets, causing low budget utilization. This contradiction between system efficacy and sample efficiency constitutes the Overscaling Curse. In this paper, we first provide a formal analysis of the overscaling curse and quantify its prevalence and severity in real-world systems. To break it, we propose Latent Budget Predictor (LanBo), which probes model latent representations to predict sample-specific optimal budgets. LanBo significantly improves budget utilization while maintaining dataset accuracy. We further integrate LanBo into the full decoding pipeline, inspiring Pre-decoding Budget Adaptation (PreAda), a paradigm that allocates budgets before decoding to preserve decoding-time parallelization. LanBo substantially improves hardware-aware efficiency in latency and memory, demonstrating both its practical value and the promise of LanBo for efficient parallel decoding.
-
GUITAR: Structured Failure Diagnosis of GUI Agents via State Transitions
Shaoqing Zhang, Kehai Chen, Xuefeng Bai, Zhuosheng Zhang, Pengfei Zhang, Yang Xiang, Min Zhang.
NeurIPS, 2026
[Paper] -
MineExplorer: Evaluating Open-World Exploration of MLLM Agents in Minecraft
Tianjie Ju, Yueqing Sun, Zheng Wu, Wei Zhang, Yaqi Huo, Xi Su, Qi Gu*, Xunliang Cai, Gongshen Liu, Zhuosheng Zhang*.
EMNLP, 2026
[Paper] []MineExplorer24Data789total
meituan-longcat/MineExplorer789Cumulative downloads across 1 dataset repositories. Each repository is counted once; downloads are not unique users.
Multimodal large language models (MLLMs) have shown strong capabilities in perception, reasoning, and action generation. However, their ability to sustain exploration in dynamic open worlds remains unclear. Existing embodied and game-based benchmarks often compress interaction into short-horizon tasks or entangle success with domain-specific game mechanics. In this paper, we introduce MineExplorer benchmark for evaluating open-world exploration capabilities of MLLM agents in Minecraft. We first filter atomic tasks whose solutions rely heavily on Minecraft-specific knowledge to better reflect general open-world reasoning. Then we organize the benchmark around a ReAct-style capability formulation and compose atomic tasks into implicit multi-hop tasks. To further construct reliable instances, MineExplorer uses a multi-agent synthesis workflow that jointly designs task graphs, sandbox scenes, and rule-based milestone evaluators. Human evaluation shows that the multi-agent synthesis workflow produces significantly more reliable instances than a single-agent baseline. Experiments with advanced MLLM agents show that open-world exploration remains challenging, as strong models can handle many single-hop tasks but degrade sharply when hidden prerequisites must be coordinated over longer trajectories. Further analysis finds that task difficulty tracks agent completion, and larger models or thinking modes do not consistently translate into better performance.
-
GradSentry: Gradient Spectral Entropy for Backdoor Sample Filtering in Large Language Model Fine-Tuning
Haodong Zhao, Tianyi Xu, Tianhang Zhao, Zhuosheng Zhang*, Gongshen Liu*.
EMNLP, 2026
[Paper] []Fine-tuning Large Language Models with untrusted data exposes models to backdoor attacks, where poisoned samples cause targeted misbehavior. Existing sample-filtering defenses rely on clustering, which requires sufficient data and can fail at extreme poison ratios. We propose GradSentry({Grad}ient {Sentry}), a backdoor sample filtering method based on the spectral entropy of per-sample gradients. Our key finding is that poisoned samples produce gradients with higher spectral entropy compared to clean samples. GradSentry captures output-altering backdoor signatures using per-sample gradient spectra, avoiding pairwise sample comparisons and clustering during feature construction. Importantly, our method is training-agnostic: it works for both parameter-efficient fine-tuning methods like LoRA and full-parameter tuning, as the gradient analysis operates independently of which parameters are being updated during training. GradSentry requires no clustering, operates effectively across all poison ratios (1%--90%), and introduces minimal computational overhead (20--50ms per sample for a 7B model). Evaluation on four QA datasets and four attack types demonstrates the effectiveness of spectral entropy for backdoor detection.
-
Causal Probing for Internal Visual Representations in Multimodal Large Language Models
Zehao Deng#, Tianjie Ju#, Zheng Wu, Liangbo He, Jun Lan*, Huijia Zhu, Weiqiang Wang, Zhuosheng Zhang*.
EMNLP, 2026
[Paper] []Causal-Probing-for-Internal-Visual-Representations0Data2ktotal
hehehahi4/Vis_diff2,028Cumulative downloads across 1 dataset repositories. Each repository is counted once; downloads are not unique users.
Despite the remarkable success of Multimodal Large Language Models (MLLMs) across diverse tasks, the internal mechanisms governing how they encode and ground distinct visual concepts remain poorly understood. To bridge this gap, we propose a causal framework based on activation steering to actively probe and manipulate internal visual representations. Through systematic intervention across four visual concept categories, our results reveal a divergence in concept encoding: entities exhibit distinct localized memorization, whereas abstract concepts are globally distributed across the network. Critically, this divergence uncovers a mechanistic driver of scaling laws: increasing model depth is indispensable for encoding distributed and complex abstract concepts, whereas entity localization remains remarkably invariant to scale. Furthermore, reverse steering uncovers that blocking explicit output triggers a surge in latent activations, exposing a compensatory mechanism between perception and generation. Finally, extending our analysis to visual reasoning, we expose a disconnect between perception and reasoning although MLLMs successfully recognize geometric relations, they treat them merely as static visual features, failing to trigger the procedural execution necessary for abstract problem-solving.
-
Do GUI Agents Know When Not to Act? Enabling Conflict-Aware Termination for Multimodal GUI Agents
Zhaoyuan Huang, Tianjie Ju, Pengzhou Cheng, Zheng Wu, Yansi Li, Chuanbiao Song, Jun Lan*, Huijia Zhu, Weiqiang Wang, Zhuosheng Zhang*.
EMNLP, 2026
[Paper] []ConflictGuard1Data120total
serein356/ConflictGUI120Cumulative downloads across 1 dataset repositories. Each repository is counted once; downloads are not unique users.
Graphical user interface (GUI) agents are increasingly used to execute natural-language instructions on user interfaces, yet real users may issue infeasible instructions due to benign mistakes. A reliable agent should not only know how to act, but also when not to act. In this work, we introduce ConflictGUI, a benchmark covering instruction-internal conflicts and instruction-GUI context conflicts to study conflict-aware termination. Our evaluation reveals severe execution-biased over-compliance: agents that perform well on feasible tasks often continue to execute blindly under conflicting instructions. To mitigate this behavior, we propose ConflictGuard, an inference-time framework that aligns an agent's feasibility awareness with its action generation. ConflictGuard contains two coupled components: a feasibility verification protocol that guides the agent to assess instruction logic and GUI-side evidence before acting, and a conditional action modulation mechanism that steers agent's over-compliance into termination-oriented behavior. Experiments across five widely-used agents demonstrate that ConflictGuard improves average conflict task success rate significantly, while preserving normal GUI-task performance. These results validate that a lightweight inference-time intervention can substantially boost GUI Agent's competence to identify inappropriate execution scenarios and refrain from unnecessary actions.
-
Communication Policy Evolution for Proactive LLM Agents
Xinbei Ma#, Jiyang Qiu#, Yao Yao, Zheng Wu, Yijie Lu, Xiangmou Qu, Jiaxin Yin, Xingyu Lou*, Jun Wang*, Weiwen Liu, Weinan Zhang, Zhuosheng Zhang*, Hai Zhao*.
EMNLP, 2026
[Paper] []LLM agents have rapidly evolved into autonomous systems, yet a persistent information gap remains between users and agents: communication is costly, while users' identical preferences further limit information exchange. To investigate how agents should communicate across modalities, this paper formalizes Communication Policy, establishes textual and UI-based policies, and then evaluates communication policies across diverse environments, personas, and model combinations. Building information asymmetry for proactive agents, we set up two complementary settings, User-Agent and Planner-Executor. Experimental results reveal complementary strengths between interaction channels: text-based interaction often facilitates task performance, while structured UI improves agents' response quality and persona compliance. Motivated by that, a hybrid method combines these advantages. We further propose Communication Policy Evolution (CPE), a self-evolution framework for refining communication policies through rollout and prompt-level evolving. Without model modification, CPE achieves the best task success across multiple settings using prompt refinement alone. Our findings identify communication behavior as a critical yet underexplored design dimension for LLM agents.
-
First Things First: Teaching LLM-Based Agents to Prioritize Must-Haves before Nice-to-Haves
Tianjie Ju#, Xinyue Xu#, Wanxuan Sun, Lingxiao Diao, Gongshen Liu, Zhuosheng Zhang*, Cheng Yang*.
EMNLP, 2026
[Paper] []Recent progress in multimodal large language models (MLLMs) has fueled significant enthusiasm in their potential to act as autonomous agents for real-world tasks. However, scenarios requiring agents to fulfill users’ complex, structured requirements remain largely underexplored. In this work, we examine reasoning tasks under three distinct requirement scenarios, each defined by the feasible solution set delineated by must-have and nice-to-have requirements: (i) Must-have requirements uniquely determine a unique feasible solution; (ii) Multiple candidate solutions satisfy the must-have requirements and are prioritized via the nice-to-have requirements; and (iii) No candidate solution satisfies the must-have requirements, in which case the agent should abstain from generating a response. We evaluate state-of-the-art MLLMs on 3,649 carefully constructed problems that reflect realistic service scenarios, including e-commerce platforms, booking systems, and map-based or ride-hailing applications. Our evaluation reveals that existing MLLMs exhibit catastrophic failures in all scenarios. Specifically, these models frequently misinterpret task requirements, violate must-have requirements, and produce invalid solutions. To address this critical gap, we propose First Things First Reinforcement Learning (FTF-RL) that explicitly optimizes reasoning over multi-priority user requirements. Experimental results show that our method substantially improves the task success rate compared to strong baselines. Moreover, FTF-RL yields general effectiveness on popular logical and mathematical reasoning tasks, including LogicVista, MathVision, and MathVista. Our finding suggests that enhancing requirement comprehension provides a simple yet effective pathway toward improving the broad generalization of MLLMs.
-
Reasoning or Rambling? Exploring the Effect of Thinking on Agent Persuasion
Haodong Zhao#, Jidong Li#, Zhaomin Wu*, Tianjie Ju, Zhuosheng Zhang*, Bingsheng He, Gongshen Liu*.
EMNLP, 2026
[Paper] []Understanding persuasion is critical for the safety and reliability of multi-agent systems built on large language models (LLMs). This paper studies persuasion dynamics by contrasting general LLMs with Large Reasoning Models (LRMs) that employ explicit “thinking” processes. Through large-scale experiments on objective (MMLU) and subjective (PersuasionBench and Perspectrum) tasks, we identify Persuasion Duality: reasoning enhances an agent’s persuasive power while simultaneously increasing its resistance to persuasion. For LRMs, adding thinking content increases persuasion rates by 21 pp on average, yet reduces susceptibility to incorrect persuasion by up to 10 pp on objective tasks. Despite these gains, we uncover a critical vulnerability: persuasiveness often stems from superficial cues such as response length and repetition rather than logical validity. Non-semantic padding or repeated conclusions can match or exceed the persuasive effect of coherent reasoning, revealing a strong length bias in agents’ judgments. We further show that persuasion propagates non-linearly in multi-hop agent chains, where intermediate agents may amplify or attenuate influence depending on task subjectivity. Finally, guided by attention analysis, we propose a promptlevel adversarial argument detection method that consistently improves agent robustness
-
Chain-of-Trigger: An Agentic Backdoor that Paradoxically Enhances Agentic Robustness
Jiyang Qiu#, Xinbei Ma#, Yunqing Xu, Zhuosheng Zhang, Hai Zhao*.
EMNLP, 2026
[Paper] []The rapid deployment of large language model (LLM)-based agents in real-world applications has raised serious concerns about their trustworthiness. In this work, we reveal the security and robustness vulnerabilities of these agents through backdoor attacks. Distinct from traditional backdoors limited to single-step control, we propose the Chain-of-Trigger Backdoor (CoTri), a multi-step backdoor attack designed for long-horizon agentic control. CoTri relies on an ordered sequence. It starts with an initial trigger, and subsequent ones are drawn from the environment, allowing multi-step manipulation that diverts the agent from its intended task. Experimental results show that CoTri achieves a near-perfect attack success rate (ASR) while maintaining a near-zero false trigger rate (FTR). Due to training data modeling the stochastic nature of the environment, the implantation of CoTri paradoxically enhances the agent's performance on benign tasks and even improves its robustness against environmental distractions. We further validate CoTri on vision-language models (VLMs), confirming its scalability to multimodal agents. Our work highlights that CoTri achieves stable, multi-step control within agents, improving their inherent robustness and task capabilities, which ultimately makes the attack more stealthy and raises potential safty risks.
-
Post-quantum Cryptography in the Wild: Assessing the Readiness of Open-Source Ecosystems
Tongxin Yuan, Zhanpeng Liu, Jiashuo Liang, Zhuosheng Zhang*, Gongshen Liu, Yang Yu, Guancheng Li*.
ASE, 2026
[Paper] []The threat of cryptographically relevant quantum computers, compounded by harvest now, decrypt later attacks, has made migration to post-quantum cryptography (PQC) urgent. With PQC standards finalized and transition guidance phasing out quantum-vulnerable algorithms, the readiness of the open-source supply chain, through which cryptographic vulnerabilities propagate, remains unclear. To fill this gap, we present the first crossecosystem empirical study of sourcelevel PQC readiness. PQC Scanner is a twostage pipeline in which (i) crypto detection identifies packages with cryptographic functionality, and (ii) PQC detection produces a binary support label and sourcederived structured readiness record at the repository level using commit history, source analysis, and agent postverification. Applied to 1,117,913 packages, Stage 1 identifies 55,654 cryptorelated packages. Stage 2 evaluates their repositories for sourcelevel PQC support. A separate audit of 219 Stage 2negative repositories gives a Stage 2 recall lower bound of ≥97.48%. On a 247repository deploymentvalidation sample, agent post-verification eliminated all false positives, yielding precision of 1.000. The pipeline scales to million-package scans: at concurrency 10, it analyzes over one million packages in just over two weeks, with a median LLM cost of $0.0010 per package. Across 8 ecosystems, we find a migration gap: only 1.88% of crypto-related packages show source-level PQC support, and the repository-deduplicated rate is 1.72%. Rust leads by both counts, while NuGet/Ruby/PHP remain near zero. Source derived structured readiness records show partial support: among PQC-supporting repositories, only 19.2% satisfy the full-support criterion, with a mean migration coverage of 36%. Adoption accelerates sharply after FIPS publication (August 2024), but migration remains infrastructure-gated: key libraries such as Python’s cryptography (581M downloads/month) and framework integration layers in Java/npm still lack deployable PQC pathways, blocking downstream packages regardless of developer intent. We characterize adoption timing, bottlenecks, and community response strategies, deriving recommendations for maintainers, registry operators, and policy makers.
-
DiG-Plan: Mitigating Early Commitment for Tool-Graph Planning via Diffusion Guidance
Yansi Li, Zhuosheng Zhang*.
IJCAI-ECAI, 2026
[Paper] [arXiv] []Generating executable tool plans requires selecting appropriate subsets from tool libraries, a combinatorial search problem with an exponentially large solution space. However, we identify a critical misalignment in predominant approaches: standard autoregressive (AR) decoding suffers from early commitment, where initial token choices rigidly constrain the search trajectory. We quantify this limitation through a controlled study, demonstrating that masked denoising achieves substantially higher solution coverage than AR sampling (Pass@10: 0.943 vs. 0.320) under matched compute. Motivated by this, we propose DiG-Plan, a framework that decouples combinatorial exploration from structural refinement. DiG-Plan employs a diffusion-based proposer to generate diverse tool sets via iterative refinement, followed by an AR refiner for dependency prediction. Experiments on TaskBench and API-Bank show that DiG-Plan outperforms AR baselines by a 10% relative margin, with the largest gains on complex compositional tasks.
-
Faithful Mobile GUI Agents with Guided Advantage Estimator
Haowen Hu#, Pengzhou Cheng#, Zheng Wu, Lingzhong Dong, Gongshen Liu*, Zhuosheng Zhang*.
ICML, 2026
[Paper] []Vision-language model based graphical user interface (GUI) agents have shown strong interaction capabilities. However, they often behave unfaithfully, relying on memorized shortcuts rather than grounding actions in displayed screen evidence or user instructions. To address this, we propose Faithful-Agent, a faithfulness-first framework that reformulates GUI interaction to prioritize evidence groundedness and internal consistency. Faithful-Agent employs a two-stage pipeline: (i) a faithfulness-oriented SFT stage to instill abstainment behaviors under evidence perturbations; (ii) an RFT stage that further amplifies faithfulness by introducing the guided advantage estimator (GuAE), an anchor-based and variance-adaptive advantage tempering mechanism built upon GRPO. GuAE prevents advantage collapse in low-variance rollout groups under sparse GUI rewards, and with a thought-action consistency reward, Faithful-Agent (Stage II) elevates the Trap SR from 13.88% to 80.21% relative to the baseline, while preserving robust general instruction-following performance.
-
Zooming without Zooming: Region-to-Image Distillation for Fine-Grained Multimodal Perception
Lai Wei#, Liangbo He#, Jun Lan, Lingzhong Dong, Yutong Cai, Siyuan Li, Huijia Zhu, Weiqiang Wang, Linghe Kong, Yue Wang, Zhuosheng Zhang, Weiran Huang*.
ICML, 2026
[Paper] []Zooming-without-Zooming190Models23.1ktotal
inclusionAI/ZwZ-2B1,675inclusionAI/ZwZ-4B5,424inclusionAI/ZwZ-7B760inclusionAI/ZwZ-8B15,278Cumulative downloads across 4 model repositories. Each repository is counted once; downloads are not unique users.
Data21.6ktotal
inclusionAI/ZoomBench4,141inclusionAI/ZwZ-RL-VQA17,454Cumulative downloads across 2 dataset repositories. Each repository is counted once; downloads are not unique users.
Multimodal Large Language Models (MLLMs) excel at broad visual understanding but still struggle with fine-grained perception, where decisive evidence is small and easily overwhelmed by global context. Recent "Thinking-with-Images" methods alleviate this by iteratively zooming in and out regions of interest during inference, but incur high latency due to repeated tool calls and visual re-encoding. To address this, we propose Region-to-Image Distillation, which transforms zooming from an inference-time tool into a training-time primitive, thereby internalizing the benefits of agentic zooming into a single forward pass of an MLLM. In particular, we first zoom in to micro-cropped regions to let strong teacher models generate high-quality VQA data, and then distill this region-grounded supervision back to the full image. After training on such data, the smaller student model improves "single-glance" fine-grained perception without tool use. To rigorously evaluate this capability, we further present ZoomBench, a hybrid-annotated benchmark of 845 VQA data spanning six fine-grained perceptual dimensions, together with a dual-view protocol that quantifies the global--regional "zooming gap". Experiments show that our models achieve leading performance across multiple fine-grained perception benchmarks, and also improve general multimodal cognition on benchmarks such as visual reasoning and GUI agents. We further discuss when "Thinking-with-Images" is necessary versus when its gains can be distilled into a single forward pass. Our code is available at this https://github.com/inclusionAI/Zooming-without-Zooming.
-
SE-GA: Memory-Augmented Self-Evolution for GUI Agents
Shilong Jin, Lanjun Wang*, Zhuosheng Zhang.
ICML, 2026
[Paper] [arXiv] []SE-GA17Models37total
waterphd/SE-GA-7B37Cumulative downloads across 1 model repositories. Each repository is counted once; downloads are not unique users.
Data263total
waterphd/SE-GA-dataset263Cumulative downloads across 1 dataset repositories. Each repository is counted once; downloads are not unique users.
Autonomous Graphical User Interface (GUI) agents often struggle with multi-step tasks due to constrained context windows and static policies that fail to adapt to dynamic environments. To address these limitations, this work proposes the Self-Evolving GUI Agent (SE-GA), a novel framework that integrates hierarchical memory structures with an iterative self-improvement mechanism. At the core of our approach is Test-Time Memory Extension (TTME), which facilitates long-term planning by dynamically retrieving episodic, semantic, and experiential memories to provide salient contexts during inference. To ensure continuous learning, we introduce Memory-Augmented Self-Evolution (MASE), which is a training pipeline that adopts the data collected by TTME to stabilize and enhance the agent's foundational policy. Extensive evaluations across both offline and online benchmarks demonstrate SE-GA achieves state-of-the-art performance, reaching success rates of 89.0% on ScreenSpot and 75.8% on the challenging AndroidControl-High dataset. Furthermore, significant improvements on the AndroidWorld benchmark highlight the superior generalization to dynamic environments.
-
Agent-Dice: Disentangling Knowledge Updates via Geometric Consensus for Agent Continual Learning
Zheng Wu, Xingyu Lou, Xinbei Ma, Yansi Li, Weiwen Liu, Weinan Zhang, Jun Wang*, Zhuosheng Zhang*.
ACL, 2026
[Paper] [arXiv] []Large Language Model (LLM)-based agents significantly extend the utility of LLMs by interacting with dynamic environments. However, enabling agents to continually learn new tasks without catastrophic forgetting remains a critical challenge, known as the stability-plasticity dilemma. In this work, we argue that this dilemma fundamentally arises from the failure to explicitly distinguish between common knowledge shared across tasks and conflicting knowledge introduced by task-specific interference. To address this, we propose Agent-Dice, a parameter fusion framework based on directional consensus evaluation. Concretely, Agent-Dice disentangles knowledge updates through a two-stage process: geometric consensus filtering to prune conflicting gradients, and curvature-based importance weighting to amplify shared semantics. We provide a rigorous theoretical analysis that establishes the validity of the proposed fusion scheme and offers insight into the origins of the stability-plasticity dilemma. Extensive experiments on GUI agents and tool-use agent domains demonstrate that Agent-Dice exhibits outstanding continual learning performance with minimal computational overhead and parameter updates.
-
ParaCook: On Time-Efficient Planning for Multi-Agent Systems
Shiqi Zhang#, Xinbei Ma#, Yunqing Xu, Zouying Cao, Pengrui Lu, Haobo Yuan, Tiancheng Shen, Zhuosheng Zhang*, Hai Zhao*, Ming-Hsuan Yang*.
ACL, 2026
[Paper] [arXiv] []Large Language Models (LLMs) exhibit strong reasoning abilities for planning long-horizon, real-world tasks, yet existing agent benchmarks focus on task completion while neglecting time efficiency in parallel and asynchronous operations. To address this, we present ParaCook, a benchmark for time-efficient collaborative planning. Inspired by the Overcooked game, ParaCook provides an environment for various challenging interaction planning of multi-agent systems that are instantiated as cooking tasks, with a simplified action space to isolate the core challenge of strategic parallel planning. Through a comprehensive evaluation of state-of-the-art LLMs, we find that current approaches achieve suboptimal plans, which struggle with parallel actions or coordination. Our analysis also reveals LLMs' potential on abstract tasks where they can focus on high-level parallel optimization. ParaCook provides a scalable evaluation framework with adjustable complexity, establishing a foundation for developing and assessing time efficiency-aware multi-agent planning.
-
The Confidence Paradox: Unveiling the Latent Discriminative Power of Diffusion Large Language Models in Mathematical Reasoning
Yansi Li, Gongshen Liu, Zhuosheng Zhang*.
ACL, 2026
[Paper] []Diffusion large language models (DLLMs) have emerged as a promising alternative to autoregressive (AR) generation, uniquely offering token-level probabilities under bidirectional context. However, the semantics of their native uncertainty estimates remain underexplored. In this work, we uncover a calibration paradox inherent to the bidirectional generation mechanism of state-of-the-art DLLMs. Concretely, we demonstrate that diffusion confidence is structurally distinct from AR likelihood. Notably, LLaDA-8B is highly miscalibrated (31.2% ECE) on mathematical reasoning benchmarks, yet possesses superior discriminative power (0.826 AUROC), significantly outperforming comparable AR baselines in single-pass settings (0.611 AUROC). We diagnose that this paradox arises because diffusion confidence functions less like a probability of correctness and more like a proxy for structural consistency enabled by the model’s bidirectional access to the entire solution path. We further show that lightweight post-hoc calibration can reconcile this gap, reducing ECE by over 60% while preserving the strong ranking signal. Our findings suggest that DLLMs offer a unique, cost-efficient uncertainty signal for reasoning tasks that complements expensive AR approaches.
-
OS-Sentinel: Towards Safety-Enhanced Mobile GUI Agents via Hybrid Validation in Realistic Workflows
Qiushi Sun#, Mukai Li#, Zhoumianze Liu#, Zhihui Xie#, Fangzhi Xu, Zhangyue Yin, Kanzhi Cheng, Zehao Li, Zichen Ding, Qi Liu, Zhiyong Wu, Zhuosheng Zhang, Ben Kao, Lingpeng Kong.
ACL, 2026 (Oral)
Best Paper Award at AIWILD @ ICLR 2026
[Paper] [arXiv] []OS-Sentinel49Data1.4ktotal
OS-Copilot/MobileRisk1,386Cumulative downloads across 1 dataset repositories. Each repository is counted once; downloads are not unique users.
Computer-using agents powered by Vision-Language Models (VLMs) have demonstrated human-like capabilities in operating digital environments like mobile platforms. While these agents hold great promise for advancing digital automation, their potential for unsafe operations, such as system compromise and privacy leakage, is raising significant concerns. Detecting these safety concerns across the vast and complex operational space of mobile environments presents a formidable challenge that remains critically underexplored. To establish a foundation for mobile agent safety research, we introduce MobileRisk-Live, a dynamic sandbox environment accompanied by a safety detection benchmark comprising realistic trajectories with fine-grained annotations. Built upon this, we propose OS-Sentinel, a novel hybrid safety detection framework that synergistically combines a Formal Verifier for detecting explicit system-level violations with a VLM-based Contextual Judge for assessing contextual risks and agent actions. Experiments show that \ours achieves 10%–30% improvements over existing approaches across multiple metrics. Further analysis provides critical insights that foster the development of safer and more reliable autonomous mobile agents. Our code, environment, and data are available at https://qiushisun.github.io/OS-Sentinel-Home/.
-
EVA: Evolving Semantic Adversaries for Red-Teaming GUI Agents Against Environmental Injection Attacks
Yijie Lu#, Manman Zhao#, Tianjie Ju, Zihe Yan, Xinbei Ma, Yuan Guo, Daizong Ding, Gongshen Liu*, Zhuosheng Zhang*.
ACL, 2026
[Paper] [arXiv] []As multimodal agents are increasingly trained to operate graphical user interfaces (GUIs) to complete user tasks, they face a growing threat from indirect prompt injection, attacks in which misleading instructions are embedded into the agent's visual environment, such as popups or chat messages, and misinterpreted as part of the intended task. A typical example is environmental injection, in which GUI elements are manipulated to influence agent behavior without directly modifying the user prompt. To address these emerging attacks, we propose EVA, a red teaming framework for indirect prompt injection which transforms the attack into a closed loop optimization by continuously monitoring an agent's attention distribution over the GUI and updating adversarial cues, keywords, phrasing, and layout, in response. Compared with prior one shot methods that generate fixed prompts without regard for how the model allocates visual attention, EVA dynamically adapts to emerging attention hotspots, yielding substantially higher attack success rates and far greater transferability across diverse GUI scenarios. We evaluate EVA on six widely used generalist and specialist GUI agents in realistic settings such as popup manipulation, chat based phishing, payments, and email composition. Experimental results show that EVA substantially improves success rates over static baselines. Under goal agnostic constraints, where the attacker does not know the agent's task intent, EVA still discovers effective patterns. Notably, we find that injection styles transfer well across models, revealing shared behavioral biases in GUI agents. These results suggest that evolving indirect prompt injection is a powerful tool not only for red teaming agents, but also for uncovering common vulnerabilities in their multimodal decision making.
-
ColorBrowserAgent: Complex Long-Horizon Browser Agent with Adaptive Knowledge Evolution
Jihong Wang#, Jiamu Zhou#, Weiming Zhang, Teng Wang, Weiwen Liu, Zhuosheng Zhang, Xingyu Lou*, Weinan Zhang, Huarong Deng, Jun Wang.
ACL Industry Track, 2026
[Paper] [arXiv] []With the advancement of vision-language models, web automation has made significant progress. However, deploying autonomous agents in real-world settings remains challenging, primarily due to site heterogeneity, where generalist models lack domain-specific priors for diverse interfaces, and long-horizon instability, characterized by the accumulation of decision drift over extended interactions. To address these challenges, we introduce ColorBrowserAgent (Complex Long-Horizon Browser Agent), a knowledge-evolving agent for robust web automation. Our approach addresses these challenges through two synergistic mechanisms: human-in-the-loop knowledge adaptation that transforms sparse human feedback into reusable domain knowledge, and knowledge-aligned progressive summarization that stabilizes long interactions through memory compression. Extensive experiments on WebArena, WebChoreArena and industrial deployment show that ColorBrowserAgent consistently outperforms strong baselines. It achieves a state-of-the-art success rate of 71.2% on WebArena and maintains 47.4% performance under zero-shot transfer setting on WebChoreArena. In commercial deployment, it improves user satisfaction by 19.3% relatively, verifying its robustness in real-world scenarios.
-
ColorBench: Benchmarking Mobile Agents with Graph-Structured Framework for Complex Long-Horizon Tasks
Yuanyi Song#, Heyuan Huang#, Qiqiang Lin, Yin Zhao, Xiangmou Qu, Jun Wang, Xingyu Lou*, Weiwen Liu, Zhuosheng Zhang, Jun Wang, Zhaoxiang Wang*, Yong Yu, Weinan Zhang*.
WWW, 2026 (Oral)
[Paper] [arXiv] []ColorBench16Data229total
Norsheep/ColorBench229Cumulative downloads across 1 dataset repositories. Each repository is counted once; downloads are not unique users.
The rapid advancement of multimodal large language models has enabled agents to operate mobile devices by directly interacting with graphical user interfaces, opening new possibilities for mobile automation. However, real-world mobile tasks are often complex and allow for multiple valid solutions. This contradicts current mobile agent evaluation standards: offline static benchmarks can only validate a single predefined "golden path", while online dynamic testing is constrained by the complexity and non-reproducibility of real devices, making both approaches inadequate for comprehensively assessing agent capabilities. To bridge the gap between offline and online evaluation and enhance testing stability, this paper introduces a novel graph-structured benchmarking framework. By modeling the finite states observed during real-device interactions, it achieves static simulation of dynamic behaviors. Building on this, we develop ColorBench, a benchmark focused on complex long-horizon tasks. It supports evaluation of multiple valid solutions, subtask completion rate statistics, and atomic-level capability analysis. ColorBench contains 175 tasks (74 single-app, 101 cross-app) with an average length of over 13 steps. Each task includes at least two correct paths and several typical error paths, enabling quasi-dynamic interaction. By evaluating ColorBench across various baselines, we discover limitations of existing models and propose improvement directions and feasible technical pathways to enhance agents' performance on complex, long-horizon problems based on experimental results.
-
See, Think, Act: Teaching Multimodal Agents to Effectively Interact with GUI by Identifying Toggles
Zongru Wu, Rui Mao, Zhiyuan Tian, Pengzhou Cheng, Tianjie Ju, Zheng Wu, Lingzhong Dong, Haiyue Sheng, Zhuosheng Zhang*, Gongshen Liu*.
CVPR, 2026
[Paper] [arXiv] []StaR9Data550total
ZrW00/StaR_state_control_benchmark550Cumulative downloads across 1 dataset repositories. Each repository is counted once; downloads are not unique users.
The advent of multimodal agents facilitates effective interaction within graphical user interface (GUI), especially in ubiquitous GUI control. However, their inability to reliably execute toggle control instructions remains a key bottleneck. To investigate this, we construct a state control benchmark with binary toggle instructions from public datasets. Evaluations of existing agents demonstrate their unreliability, particularly when the current toggle state already matches the desired state. To address the challenge, we propose State-aware Reasoning (StaR), a training method that teaches agents to perceive the current toggle state, analyze the desired state from the instruction, and act accordingly. Experiments on three multimodal agents demonstrate that StaR can improve toggle instruction execution accuracy by over 30%. Further evaluations on three public benchmarks show that StaR also enhances general task performance. Finally, evaluations on a dynamic environment highlight the potential of StaR for real-world applications.
-
Training High-Level Schedulers with Execution-Feedback Reinforcement Learning for Long-Horizon GUI Automation
Zehao Deng, Tianjie Ju, Zheng Wu, Zhuosheng Zhang*, Gongshen Liu.
CVPR, 2026
[Paper] [arXiv] []CES4Data657total
hehehahi4/CES657Cumulative downloads across 1 dataset repositories. Each repository is counted once; downloads are not unique users.
The rapid development of large vision-language model (VLM) has greatly promoted the research of GUI agent. However, GUI agents still face significant challenges in handling long-horizon tasks. First, single-agent models struggle to balance high-level capabilities and low-level execution capability, facing prevalent issues of responsibility coupling and capability conflicts. Second, agents lack awareness of the task state, leading to progress loss in long-horizon tasks. To address these challenges, we propose a staged execution-feedback reinforcement learning algorithm. Unlike training a unified policy model, we focus on training high-level scheduling models. Specifically, we propose and train two agents: a Coordinator, responsible for the strategic planning and task decomposition; and a State Tracker, responsible for context compression and information management to maintain the task's state and coherence. Based on this, we built the Coordinator-Executor-State Tracker (CES) multi-agent framework, which can be integrated with any low-level Executor model, assisting the Executor in solving long-horizon tasks through task scheduling and state management. Experiments on long-horizon task benchmarks demonstrate that CES significantly enhances the system's planning and state management capabilities. Furthermore, analysis confirms that our trained high-level scheduling module is a generalizable, plug-and-play module that significantly enhances the long-horizon capabilities of various Executors.
-
LaSM: Layer-wise Scaling Mechanism for Defending Pop-up Attack on GUI Agents
Zihe Yan, Jiaping Gui*, Zhuosheng Zhang*, Gongshen Liu.
CVPR, 2026
[Paper] [arXiv] []Graphical user interface (GUI) agents built on multimodal large language models (MLLMs) have recently demonstrated strong decision-making abilities in screen-based interaction tasks. However, they remain highly vulnerable to pop-up-based environmental injection attacks, where malicious visual elements divert model attention and lead to unsafe or incorrect actions. Existing defense methods either require costly retraining or perform poorly under inductive interference. In this work, we systematically study how such attacks alter the attention behavior of GUI agents and uncover a layer-wise attention divergence pattern between correct and incorrect outputs. Based on this insight, we propose LaSM, a Layer-wise Scaling Mechanism that selectively amplifies attention and MLP modules in critical layers. LaSM improves the alignment between model saliency and task-relevant regions without additional training. Extensive experiments across 12 types of pop-up perturbations and 4 different model backbones show that LaSM consistently enhances the defense success rate. When combined with prompt-level alerts, LaSM achieves over 98% robustness even under strong inductive attacks. Our findings reveal that attention misalignment is a core vulnerability in MLLM agents and can be effectively addressed through selective layer-wise modulation.
-
Discourse-Aware Language Representation
Zhuosheng Zhang, Siru Ouyang, Hai Zhao.
IEEE Transactions on Pattern Analysis and Machine Intelligence, 2026
[Paper] []Recent Transformer-based language representation techniques have commonly adopted a straightforward approach to modeling textual context as a linear sequence of successive tokens. However, this sequential modeling strategy falls short in actively exploring intermediate structures present in natural languages and does not account for the rich interactive relationships between sentences. To overcome these limitations, we propose a discourse-aware framework that bridges the gap between sequential contextualization and the interactive nature of conversational reading comprehension. Concretely, we first divide the context into elementary discourse units (EDUs), ensuring that each unit contains precisely one condition. Then, we systematically explore three instantiations for modeling discourse features: sequential EDU encoding, discourse-aware masking, and discourse graph network. These techniques allow us to capture the nuanced interactions within the discourse. To assess the efficacy of our methodologies, we perform experiments on three conversational reading comprehension tasks: multi-turn response selection, conversational question answering, and conversational machine reading. Experimental results demonstrate the superiority of our proposed approach. Moreover, analysis reveals that the discourse-aware approach enables the model to effectively capture intricate relationships within the context and fosters reasoning interpretability. Additionally, our method exhibits efficacy across various backbone PLMs and diverse domains.
-
Mobile-Aptus: Confidence-Driven Proactive and Robust Interaction in MLLM-Based Mobile-Using Agents
Zheng Wu#, Pengzhou Cheng#, Zongru Wu, Yuan Guo, Tianjie Ju, Aston Zhang, Gongshen Liu, Zhuosheng Zhang*.
IEEE Transactions on Audio, Speech and Language Processing, 2026
[Paper] [arXiv] []Recent advancements in multimodal large language models (MLLMs) have shown exceptional potential in enabling mobile-using agents to autonomously execute human instructions. However, fully automated agents often try to execute tasks even when they are unable to resolve them, leading to the problem of over-execution. Previous studies solve it by training a interactive mobile-using agents to let agents request human interaction when agents can not complete user instructions. However, we find that these interactive agents tend to exhibit over-soliciting behavior, relying excessively on human intervention. To mitigate both over-execution and over-soliciting, we propose a universal confidence integration framework that enables confidence-driven proactive and robust interaction in MLLM-based mobile-using agents. The framework consists of two stages: interaction capability empowerment and confidence bias correction. In the interaction capability empowerment stage, agents learn through supervised fine-tuning to output both actions and confidence scores. In the confidence bias correction stage, agents learn to output more accurate confidence scores by combining semantic similarity retrieval with direct preference optimization. Experimental results show Mobile-Aptus achieves state-of-the-art performance on the four popular mobile-using agent benchmarks: OS-Kairos, AITZ, Meta-GUI, and AndroidControl. Mobile-Aptus consistently outperforms all baselines in offline benchmarks, with an average improvement over 17% in task success rate. In real-world dynamic experiments, Mobile-Aptus surpasses the baseline by 26% in task success rate with only 0.64 intervention steps per instruction. The codes are available at https://github.com/Wuzheng02/Mobile-Aptus.
-
Beyond Elicitation: Provision-Based Prompt Optimization for Knowledge-Intensive Tasks
Yunzhe Xu, Zhuosheng Zhang, Zhe Liu*.
IEEE Transactions on Audio, Speech and Language Processing, 2026
[Paper] [arXiv] []While prompt optimization has emerged as a critical technique for enhancing language model performance, existing approaches primarily focus on elicitation-based strategies that search for optimal prompts to activate models' capabilities. These methods exhibit fundamental limitations when addressing knowledge-intensive tasks, as they operate within static knowledge capacity rather than providing the factual knowledge, terminology precision, and reasoning patterns required in specialized domains. To address these limitations, we propose Knowledge-Provision-based Prompt Optimization (KPPO), a framework that reformulates prompt optimization as systematic knowledge integration rather than potential elicitation. KPPO introduces three key innovations: 1) a knowledge gap filling mechanism for knowledge gap identification and targeted remediation; 2) a batch-wise candidate evaluation approach that considers both performance improvement and distributional stability; 3) an adaptive knowledge pruning strategy that balances performance and token efficiency, reducing up to 29% of inference token usage. Evaluation on 15 knowledge-intensive benchmarks from various domains demonstrates KPPO's superiority over elicitation-based methods, with an average improvement of ~6% over baselines while achieving comparable or lower token consumption.
-
Flooding spread of manipulated knowledge in LLM-based multi-agent communities
Tianjie Ju, Yiting Wang, Yi Hua, Xinbei Ma, Pengzhou Cheng, Haodong Zhao, Yulong Wang, Lifeng Liu, Jian Xie, Zhuosheng Zhang*, Gongshen Liu*.
Science China Information Sciences, 2026
[Paper] [arXiv] []The rapid adoption of large language models (LLMs) in multi-agent systems has highlighted their impressive capabilities in various applications, such as collaborative problem-solving and autonomous negotiation. However, the security implications of these LLM-based multi-agent systems have not been thoroughly investigated, particularly concerning the spread of manipulated knowledge. In this paper, we investigate this critical issue by constructing a detailed threat model and a comprehensive simulation environment that mirrors real-world multi-agent deployments on a trusted platform. Subsequently, we propose a novel two-stage attack method involving Persuasiveness Injection and Manipulated Knowledge Injection to systematically explore the potential for manipulated knowledge (i.e., counterfactual and toxic knowledge) spread without explicit prompt manipulation. Our method leverages the inherent vulnerabilities of LLMs in handling world knowledge, which can be exploited by attackers to unconsciously spread fabricated information. Through extensive experiments, we demonstrate that our attack method can successfully induce LLM-based agents to spread both counterfactual and toxic knowledge without degrading their foundational capabilities during agent communication. Furthermore, we show that these manipulations can persist through popular retrieval-augmented generation frameworks, where several benign agents store and retrieve manipulated chat histories for future interactions. This persistence indicates that even after the interaction has ended, the benign agents may continue to be influenced by manipulated knowledge. To mitigate the potential risk, we additionally propose two defense strategies by designing system prompts to encourage agents to critically verify the knowledge they share and incorporating supervisory agents to oversee interactions. Results demonstrate that those strategies can effectively reduce the spread success rate. Code is publicly available at https://github.com/Jometeorie/KnowledgeSpread .
-
Auditing Partial Dataset Usage in Large Language Models Via Fuzzy Membership Aggregation
Hongyu Zhu, Sichu Liang, Bofan Chen, Shi-Lin Wang, Zhuosheng Zhang, Weiping Ding.
IEEE Transactions on Fuzzy Systems, 2026
[Paper] []The remarkable capabilities of Large Language Models (LLMs) are fueled by massive internet-scale corpora. However, scraped data owners often do not consent to its use for training, raising significant legal and ethical concerns over copyright and privacy. Data auditing techniques seek to verify whether a protected dataset was used in training a target LLM, typically framing the task as membership inference: estimating binary sample-level membership and aggregating to a dataset-level decision. In this paper, we identify a fundamental limitation of this crisp binary paradigm: in realistic training pipelines, datasets are rarely used in full. Instead, models are trained on mixtures of partial subsets drawn from multiple sources. Existing auditing techniques, built upon an all-or-none assumption—declaring a dataset either entirely present or absent from training—collapse in partial dataset usage scenarios. Their predictions fluctuate unpredictably with the member ratio, causing unstable performance and high false-negative rates. Inspired by fuzzy set theory, we relax the crisp notion of binary membership to a continuous fuzzy membership in [0,1], quantifying each sample's degree of inclusion in the model's training set. We establish a theoretical bridge between sample-level fuzzy memberships and the dataset-level usage ratio, facilitating inference of the proportion of a protected dataset used during training. A neural network fuzzifier first estimates sample-level fuzzy memberships from binary labels in a reference set, then refines them using dataset-level member ratios as higher-order supervision. Finally, a defuzzification stage aggregates calibrated memberships to determine partial usage. Across LLMs of varying scales and multiple auditing datasets, our Fuzzy Auditor substantially outperforms state-of-the-art crisp binary techniques in detecting partial usage, estimating member proportions, and identifying individual member samples.
-
Generalizable and Adaptive Continual Learning Framework for AI-generated Image Detection
Hanyi Wang, Jun Lan, Yaoyu Kang, Huijia Zhu, Weiqiang Wang, Zhuosheng Zhang, Shilin Wang*.
IEEE Transactions on Multimedia, 2026
[Paper] [arXiv] []The malicious misuse and widespread dissemination of AI-generated images pose a significant threat to the authenticity of online information. Current detection methods often struggle to generalize to unseen generative models, and the rapid evolution of generative techniques continuously exacerbates this challenge. Without adaptability, detection models risk becoming ineffective in real-world applications. To address this critical issue, we propose a novel three-stage domain continual learning framework designed for continuous adaptation to evolving generative models. In the first stage, we employ a strategic parameter-efficient fine-tuning approach to develop a transferable offline detection model with strong generalization capabilities. Building upon this foundation, the second stage integrates unseen data streams into a continual learning process. To efficiently learn from limited samples of novel generated models and mitigate overfitting, we design a data augmentation chain with progressively increasing complexity. Furthermore, we leverage the Kronecker-Factored Approximate Curvature (K-FAC) method to approximate the Hessian and alleviate catastrophic forgetting. Finally, the third stage utilizes a linear interpolation strategy based on Linear Mode Connectivity, effectively capturing commonalities across diverse generative models and further enhancing overall performance. We establish a comprehensive benchmark of 27 generative models, including GANs, deepfakes, and diffusion models, chronologically structured up to August 2024 to simulate real-world scenarios. Extensive experiments demonstrate that our initial offline detectors surpass the leading baseline by +5.51% in terms of mean average precision. Our continual learning strategy achieves an average accuracy of 92.20%, outperforming state-of-the-art methods.
-
Domain Adaptation of MLLM-Based GUI Agents in Documentation-Rich Environments with Standard Operating Procedures
Lingzhong Dong, Ziqi Zhou, Pengzhou Cheng, Zongru Wu, Zheng Wu, Gongshen Liu*, Zhuosheng Zhang*.
KSEM, 2026
[Paper] []The rapid progress of multimodal large language models (MLLMs) has driven growing interest in autonomous MLLM-based agents, particularly for graphical user interface (GUI) interaction. Although existing MLLM-based GUI agents achieve strong performance on general-purpose benchmarks, their effectiveness degrades significantly in vertical domains. In this work, we focus on documentation-rich vertical domains, where systems are accompanied by user manuals that encode implicit procedural knowledge. To systematically study this problem, we construct a benchmark of high-frequency, realistic cockpit commands that reflect real-world usage patterns. We propose AutoSOP, a standard operating procedure (SOP)-aware planning framework that enhances GUI agents by incorporating domain knowledge from user manuals. AutoSOP converts manuals into structured SOPs represented as page-transition logic, which is explicitly injected into the agent’s planning stage. By constraining action generation with SOP-guided plans, AutoSOP reduces hallucinated actions without requiring modifications to the underlying MLLM backbones, while remaining compatible with existing GUI agent frameworks. Extensive experiments across diverse MLLM backbones demonstrate that AutoSOP consistently improves success rates (SR), yielding up to 20% absolute gains in SR on out-of-distribution tasks. Further ablation studies and fine-grained analyses show that SOP-guided planning is the key contributor to these improvements, enabling both more reliable decision-making and interpretable insights into GUI agent behavior in vertical domains.
-
Thinking In a Crowd: How Auxiliary Information Shapes LLM Reasoning
Haodong Zhao#, Chenyan Zhao#, Yansi Li, Zhuosheng Zhang*, Gongshen Liu*.
ICASSP, 2026
[Paper] [arXiv] []Data553total
billhdzhao/SciAux553Cumulative downloads across 1 dataset repositories. Each repository is counted once; downloads are not unique users.
The capacity of Large Language Models (LLMs) to reason is fundamental to their application in complex, knowledge-intensive domains. In real-world scenarios, LLMs are often augmented with external information that can be helpful, irrelevant, or even misleading. This paper investigates the causal impact of such auxiliary information on the reasoning process of LLMs with explicit step-by-step thinking capabilities. We introduce SciAux, a new dataset derived from ScienceQA, to systematically test the robustness of the model against these types of information. Our findings reveal a critical vulnerability: the model's deliberative "thinking mode" is a double-edged sword. While helpful context improves accuracy, misleading information causes a catastrophic drop in performance, which is amplified by the thinking process. Instead of conferring robustness, thinking reinforces the degree of error when provided with misinformation. This highlights that the challenge is not merely to make models "think", but to endow them with the critical faculty to evaluate the information upon which their reasoning is based. The SciAux dataset is available at https://huggingface.co/datasets/billhdzhao/SciAux.
-
GEM: Gaussian Embedding Modeling for Out-of-Distribution Detection in GUI Agents
Zheng Wu, Pengzhou Cheng, Zongru Wu, Lingzhong Dong, Zhuosheng Zhang*.
AAAI, 2026
[Paper] [arXiv] []Graphical user interface (GUI) agents have recently emerged as an intriguing paradigm for human-computer interaction, capable of automatically executing user instructions to operate intelligent terminal devices. However, when encountering out-of-distribution (OOD) instructions that violate environmental constraints or exceed the current capabilities of agents, GUI agents may suffer task breakdowns or even pose security threats. Therefore, effective OOD detection for GUI agents is essential. Traditional OOD detection methods perform suboptimally in this domain due to the complex embedding space and evolving GUI environments. In this work, we observe that the in-distribution input semantic space of GUI agents exhibits a clustering pattern with respect to the distance from the centroid. Based on the finding, we propose GEM, a novel method based on fitting a Gaussian mixture model over input embedding distances extracted from the GUI agent that reflect its capability boundary. Evaluated on eight datasets spanning smartphones, computers, and web browsers, our method achieves an average accuracy improvement of 23.70% over the best-performing baseline while only increasing training time by 4.9% and testing time by 6.5%. We also experimentally demonstrate that GEM can improve the step-wise success rate by 9.40% by requesting assistance from the cloud model when encountering OOD samples. Analysis verifies the generalization ability of our method through experiments on nine different backbones.
-
An LLM-based Quantitative Framework for Evaluating High-Stealthy Backdoor Risks in OSS Supply Chains
Zihe Yan#, Kai Luo#, Haoyu Yang, Yang Yu, Zhuosheng Zhang*, Guancheng Li*.
AAAI, 2026
[Paper] [arXiv] []In modern software development workflows, the open-source software supply chain contributes significantly to efficient and convenient engineering practices. With increasing system complexity, using open-source software as third-party dependencies has become a common practice. However, the lack of maintenance for underlying dependencies and insufficient community auditing create challenges in ensuring source code security and the legitimacy of repository maintainers, especially under high-stealthy backdoor attacks exemplified by the XZ-Util incident. To address these problems, we propose a fine-grained project evaluation framework for backdoor risk assessment in open-source software. The framework models stealthy backdoor attacks from the viewpoint of the attacker and defines targeted metrics for each attack stage. In addition, to overcome the limitations of static analysis in assessing the reliability of repository maintenance activities such as irregular committer privilege escalation and limited participation in reviews, the framework uses large language models (LLMs) to conduct semantic evaluation of code repositories without relying on manually crafted patterns. The framework is evaluated on sixty six high-priority packages in the Debian ecosystem. The experimental results indicate that the current open-source software supply chain is exposed to various security risks.
Shared Tasks
[May 2022] HellaSwag Leaderboard on Commonsense Reasoning- The best among all submissions. [Leaderboard] [Paper]
- The best among all submissions. [Leaderboard] [Paper]
- The best among all submissions. [Leaderboard] [Paper]
- The best models for both single and ensemble settings among all submissions (2020.01).
- The first to surpass human benchmark on both EM and F1 scores with a single model (from 2019.07-09).
- The first time to exceed 90% F1 score with ensemble models.
[Leaderboard] [Paper] [Report] - The best among all submissions.
- The best among all academic submissions.
[Leaderboard] [Paper] [Report] - The best among all submissions.
[Leaderboard] [Paper] - The 3rd best among all submissions.
- The best among all academic submissions.
[Leaderboard] [Paper] - The best single system and the second ensemble system (Silver Medal).
[Leaderboard] [Paper] [Source]
Awards & Honors
-
2024: WAIC Youth Outstanding Paper Award, World Artificial Intelligence Conference.
-
2024: WAIC YunFan Award: Bright Star, World Artificial Intelligence Conference.
-
2023: Excellent Doctoral Thesis of Chinese Information Processing Society (CIPS).
-
2023: Shanghai Outstanding Doctoral Graduate.
-
2022: Academic Stars of Graduate Students (10 recipients), Shanghai Jiao Tong University.
-
2021: Global Top 100 Chinese Rising Stars in Artificial Intelligence (Top 10 recommended), Baidu Research.
-
2021: Baidu Scholarship (10 recipients, worldwide), Baidu.
-
2020: National Scholarship of China, Ministry of Education of the P.R. China.
-
2019: Yang Yuanqing Education Fund, The foundation of Class 1988 in CS @ Shanghai Jiao Tong University.
-
2018: Academic Stars of Graduate Students (The only master student awardee), Shanghai Jiao Tong University.
-
2016: National Figures Nomination of College Students (20 total recipients), Ministry of Education of the P.R. China.
-
2015: CCF Elite Collegiate Award, China Computer Federation.
Academic Service
Organization:- Co-chair of Tutorial Session at CCL 2026
- Organizing Committee Member of CJNLP 2025
- Co-chair of Hot Paper Session at CCL 2025
- Session Chair at RL China 2024
- Session Chair at CJNLP 2024
- Session Chair at IJCNLP-AACL 2023
- Co-chair of Student Seminar at CCL 2022
- President of IBM Tech Club at Wuhan University, 2014-2015
- AAAI 2026
- ACL Rolling Review
- NeurIPS 2025
- EMNLP 2025
- ACL 2025
- LREC-COLING 2024
- IJCAI 2024
- ICLR 2023 TinyPapers
- ML/AI conferences: ICLR, ICML, NeurIPS, AAAI, IJCAI, etc.
- CL/NLP conferences: ARR, ACL, EMNLP, COLING, NAACL, AACL, NLPCC, CCL, etc.
- Artificial Intelligence, IEEE/ACM TASLP, IEEE TNNLS, IEEE TETCI, IEEE Communications Magazine, ACM TALLIP, ACM TOIS, TMLR, Neurocomputing, Multimedia Systems, Neural Computing and Applications, Expert Systems With Applications.
Experience
-
Jul. 2022 - Aug. 2023, Amazon Web Services AI, CA, USA.
Applied Scientist Intern, advised by Dr. Aston Zhang, Mu Li, Alex Smola. -
Feb. 2022 - June. 2022, Microsoft Cognitive Services Research Group, WA, USA.
Research Intern, advised by Dr. Shuohang Wang. -
Mar. 2021 - Dec. 2021, Langboat Tech, Beijing, China.
Research Intern, advised by Prof. Ming Zhou. -
Jun. 2019 - Jul. 2020, NICT, Kyoto, Japan.
Internship Research Fellow, advised by Prof. Rui Wang, Kehai Chen, Masao Utiyama, and Eiichiro Sumita.
Education
-
Sept. 2020 - Sept. 2023
Ph.D., Dept. of Computer Science and Engineering, Shanghai Jiao Tong University, advised by Prof. Hai Zhao. -
Sept. 2016 - Mar. 2020
M.S., Dept. of Computer Science and Engineering, Shanghai Jiao Tong University, advised by Prof. Hai Zhao. -
Sept. 2012 - Jun. 2016
B.S., Dept. of Computer Science and Engineering, Wuhan University, advised by Prof. Haojun Ai.
Research Team
PhD Students:- 2027 (incoming): Zehao Deng
- 2026: Yijie Lu
- 2025: Yansi Li
- 2024: Zihe Yan
- 2023: Yiming Wang (co-advising with Prof. Rui Wang)
- 2022: Zongru Wu (co-advising with Prof. Gongshen Liu), Pengzhou Cheng (co-advising with Prof. Gongshen Liu; currently Lecturer at Shanghai University)
- 2021: Xinbei Ma (co-advising with Prof. Hai Zhao; currently Postdoc at NUS), Zhiwei He (co-advising with Prof. Rui Wang; currently at MiniMax), Tianjie Ju (co-advising with Prof. Gongshen Liu; currently Postdoc at NUS), Haodong Zhao (co-advising with Prof. Gongshen Liu, 入选中国科协青年科技人才培育工程博士生专项计划、腾讯犀牛鸟精英人才计划; incoming Postdoc at NUS, Dec. 2026)
- 2027 (incoming): Zhaoyuan Huang, Manman Zhao
- 2026: Haowen Hu, Qilin Zhou
- 2025: Zheng Wu (获评上海交通大学2025届优异学士学位论文), Lingxiao Diao, Zhuzuoken Xuan
- 2024: Lingzhong Dong
- 2023: Tongxin Yuan, co-advising with Prof. Gongshen Liu ( → Tencent Xuanwu Lab)
- 2022: Anni Zou, co-advising with Prof. Hai Zhao (currently Researcher at Alibaba Tongyi Lab)
- 2026: Yuan Guo
- 2025: Yiting Wang ( → MS at UCSD), Xuanchang Zhang ( → RA at UIUC; incoming PhD at UIUC)
- 2024: Yexin Wu ( → MS at UIUC)
- 2023: Sizhe Zhou ( → MS at UIUC; currently ML Engineer at Adobe)
- 2022: Siru Ouyang ( → PhD at UIUC; currently Technical Staff at OpenAI), Jialin Chen ( → PhD at Yale University), Junlong Li ( → MS at SJTU; currently PhD at HKUST), Dongjie Yang ( → PhD at SJTU; currently at Tencent Hunyuan), Yuchen He ( → MS at SJTU; currently PhD at SJTU)
- 2021: Longxiang Liu ( → MS at ICT/CAS; currently at ByteDance Seed)
- 2020: Yuwei Wu ( → MS at CMU)